Hyperliquid historical S3 archive
Discover Reservoir by Hydromancer, our free tool for looking back at all of HyperCore’s onchain archive.
Free, forever Hyperliquid historical data — introducing Reservoir
Looking for Hyperliquid's historical data? Reservoir is the free, forever Hyperliquid historical data S3 archive — every market, straight from S3, with no paywall, no API key, and no subscription. Pull what you need at Reservoir Docs.
Access full Hyperliquid data archive here→
Why we built Reservoir?
We built Reservoir because Hyperliquid’s onchain transparency wasn’t matched by easy access to its historical data.
We've been building on Hyperliquid since 2024, and have been in the business of infra and data provision for builder-code apps, market makers, and businesses since mid-2025.
Hyperliquid is one of the few venues where everything is onchain and transparent — order flow, token buybacks, builder-code earnings, liquidation levels, deposits/withdrawals, and everything else. It is what lets anyone — not just the exchange or insiders — ask questions that matter and get data-driven answers.
- How organic is the volume?
- How strong is user retention?
The problem was that historical data was not easily accessible — HyperCore does not have an archival node, so users had to rely on the Hyperliquid Foundation (or someone else!) to upload the data.
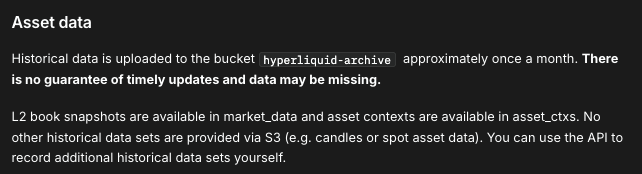 Historical data was uploaded to the bucket by the Foundation, without any guarantees, on a best-effort basis. Besides, HIP-3 trade data was not uploaded at all.
This felt like a wrong default.
This was apparent to us when we started receiving inbound from different people curious about Hyperliquid traction, asking us whether the HIP-3 RWA volumes are real, and how they can verify the trades, volume, and user retention. We realized that there needs to be a way to verify clean, correct data, for free — so we did something about it.
What's in the Reservoir
Reservoir covers the full breadth of Hyperliquid market data, such as:
- Validator perps and the crypto perps on the main DEX, HIP-3 perps from every deployer — Trade[XYZ], Ventuals, Felix, Markets.xyz, Dreamcash, HyENA, and Paragon — each with complete history back to its launch, plus HIP-4 markets when they launch.
- Any markets data that's ever traded on Hyperliquid.
Getting at it is straightforward by design. The data lives as S3 archives, so there's no bespoke API to learn, no key to provision, and no rate limit to negotiate around — you point DuckDB, Polars, or pandas at a path and query.
That simplicity is deliberate: the less that stands between a question and the data, the more people will actually verify things for themselves, which is the whole reason Reservoir exists. We'll keep widening coverage and adding datasets as people tell us what they need.
Four datasets are live on Reservoir :
#1: Fills — every trade, liquidation, ADL, builder & TWAP fillEvery execution across all perpetual and spot markets, on Hyperliquid and all HIP-3 dexes. Liquidations, ADLs, builder fills, TWAP fills, and spot are carved out as their own sub-datasets for convenience, and each fill carries a full 27-column schema — price, size, side, direction, realized PnL, fees (including builder and deployer fees and priority gas), wallet address, liquidation detail, and more.
Good for: volume studies, PnL and retention analysis, liquidation cascades, builder-flow attribution.
#2: Candles — 1-second OHLCVOne-second OHLCV for every perp and spot market on every dex, backfilled before the cutoff date (see Coverage). Roll it up to 1m, 5m, 1h, or any interval you like yourself.
Good for: backtesting, microstructure work, volatility and volume curves.
#3: Snapshots — daily positions, balances, account valuesA daily snapshot of every trader's open positions, spot token balances, and account values.
Good for: open-interest reconstruction, position concentration and whale-watching, leverage and account-mode breakdowns.
#4: Orderbook — 20-level L2 snapshotsTwenty levels of L2 Hyperliquid orderbook data — price, size, and order count per level — captured at a one-minute cadence for every perp and spot market on every dex.
Good for: spread, depth, and liquidity analysis, slippage modeling, market-maker research.
Reservoir is updated daily, with orderbook snapshots refreshed weekly.
How to access it (S3, requester-pays)
Reservoir lives in a single public S3 bucket — s3://hydromancer-reservoir, region ap-northeast-1.
The data is free. It's a requester-pays bucket, which is the standard way to publish open datasets at this scale (Hyperliquid's own hyperliquid-archive works the same way): you query it from your own AWS account and pay only AWS's normal request and egress costs for what you actually pull. There's no subscription, no API key, and no rate limit or metering from us — the bucket stays open precisely because nobody can drain it on someone else's dime.
Everything is Parquet, so any tool that reads Parquet from S3 works: DuckDB, Polars, pandas/pyarrow, Spark, and the rest. The fastest path from zero to a result is DuckDB — install the S3 extension, set the region, and read straight from a path:
INSTALL httpfs; LOAD httpfs;SET s3_region = 'ap-northeast-1';SELECT *FROM read_parquet( 's3://hydromancer-reservoir/by_dex/hyperliquid/fills/perp/all/date=2026-03-22/fills.parquet')WHERE coin = 'BTC';
That's the whole onboarding. Swap the path for any dataset, glob across dates with date=*, and you have queryable Hyperliquid S3 data in one statement. For the exact paths, partition layout, and every column, see the Reservoir docs.
Reservoir vs. the official Hyperliquid S3 archive
Hyperliquid's Foundation publishes its own historical bucket, hyperliquid-archive, and it's a genuine public good — it's why anyone could do on-chain research in the first place.
But it was built as a best-effort archive, not a maintained data product, and the gaps are exactly the ones that bite when you sit down to actually study the market.
Here's the side-by-side comparison:
| Feature | Official hyperliquid-archive | Reservoir |
|---|---|---|
| Cadence | ~Monthly uploads, no guarantee of timeliness; data may be missing | Daily |
| Coverage | Validator perps only | Entire Hyperliquid surface, including all HIP-3 deployers |
| Candles | None via S3 (record them yourself via the API) | 1-second OHLCV, aggregate to any interval |
| Spot history | Not provided via S3 | Spot fills + daily spot balances |
| Cost model | Standard requester-pays S3 | Standard requester-pays S3 — free data |
| Commitment | Best-effort basis | Commitment to daily uploads and highest standards of data integrity |
None of this is a knock on the official archive — it's the right baseline, and hyperliquid-archive remains the original, canonical source.
Reservoir is the maintained, complete, research-ready layer on top: the same Hyperliquid historical S3 archive idea, kept current daily, extended to HIP-3 and candles, and cleaned so you can trust what you query without second-guessing the source. With a strong commitment to preserve it this way.
Why is it free, forever? (Are we insane?)
Reservoir is a clean, deduplicated, daily-maintained mirror of Hyperliquid's history that anyone can pull and inspect for themselves, whether you're a researcher, a journalist, a trader, or a builder. Everything Hyperliquid, in S3, free.
We maintain the highest standards of data integrity. We receive the data from multiple Hyperliquid nodes, clean and deduplicate it, run checks, and then upload it as structured datasets.
Why is Reservoir free?
We'll be upfront about our incentive, too. We're a data company, and an ecosystem where people genuinely study Hyperliquid — and build on it — is good for us as much as it's good for Hyperliquid. Giving the historical data away costs us little and makes the whole space easier to reason about. That's a trade we're happy to make, and happy to say out loud.
At the end of the day, if people use the data to backtest, eventually they will want to run their systems in prod.
We'll be there to help with the highest-quality data streams as well.
About Hydromancer
Hydromancer is a Hyperliquid data provider built for people who need the numbers to be right. We've been on Hyperliquid since 2024, and more than 80 builders — app teams, HIP-3 deployers, and market makers — already run on our stack. We deliver the highest-quality, lowest-latency Hyperliquid market data available anywhere, which is what lets us position as one of the leading Hyperliquid infrastructure providers rather than just claim it: the builder count and the live product are the proof.
Reservoir is the free, historical side of that work. If you're a developer who's moved past backtesting and needs the most reliable Hyperliquid L1 data service in production — real-time orderbook streaming, builder-grade API schemas, WebSocket feeds — that's our data-streaming product, and we'd love to help. Early-stage team? Check out the Hydromancer for early-stage teams program. 🌱
Read next
Exploring the Reservoir Data
Explore Reservoir's Hyperliquid historical data fills, candles, snapshots and order books, with tested examples for extracting selected markets, wallets and time ranges.
Read ↗
How to get Hyperliquid data
The official API only serves the last 10,000 fills. Discover how Reservoir gives you every Hyperliquid fill, candle, and book for free.
Read ↗
Hyperliquid API Guide for Builders
A builder's guide to the Hyperliquid API: which endpoint answers which question, API keys, testnet USDC, tested limits and common mistakes, with code.
Read ↗